Manav Pandey
I build agentic systems and the harnesses they run in, from the GenAI frameworks and agent harness that thousands of developers use at American Express to open-source tools that coordinate teams of coding agents. I care most about alignment: agents that do what we intended, with evidence a person can check.
Currently a Senior AI Research Engineer at American Express and an M.S. student at Georgia Tech. I’m building Verifold, an open-source workspace where a team of coding agents runs research together, and Automative, an improvement loop where the model never grades its own work.
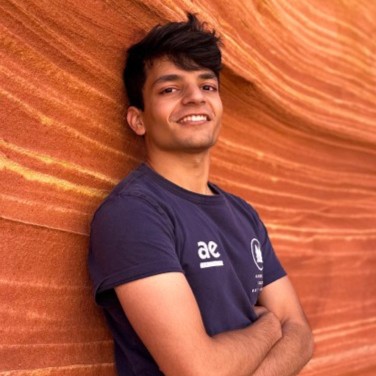
If I had to describe myself
01I build the harnesses that agents run in: what they can see, what they may do, and how a person checks their work.
Agent Engineer.
02I’ve fine-tuned, quantized, and deployed open-weight models in production — the kind of work where inference latency and model quality both matter.
ML Engineer.
At Lightsource I was the sole ML engineer: vLLM serving across multiple GPUs, dynamic LoRA adapters, DPO and PPO fine-tuning of Mistral and Mixtral, INT4-FP8 quantization for production inference. At Amex I built the internal model routing and tooling layer that sits between developers and LLMs. The craft is making models work reliably at scale, not just on a notebook.
03My research question is alignment: can we tell when a model or an agent stops doing what we intended, and prove it with evidence?
Researcher.
My paper on sycophancy and lying (ICML 2026 workshop poster) found that across twelve open-weight models, the same attention heads flag a claim as wrong whether the model judges it alone or is pressured to agree. The model knows, and agrees anyway. I bring the same skepticism to agents: Automative re-checks every gain on held-out data, and I reproduce results before I trust them. I’m studying ML formally at Georgia Tech while I keep building in this direction.
Experience
Senior AI Research Engineer
American Express — Enterprise Data & AI R&D
- Built and shipped one of American Express’s first agentic use cases in production using LangGraph and MCP.
- Lead GPU Inference Engineer for enterprise GPU consolidation — adapting vLLM’s inference API to run on the KAI Scheduler, with dynamic routing and model serving across thousands of concurrent requests.
- Lead engineer on internal GenAI frameworks serving 1,500+ developers — building Amex-native equivalents of LangChain, LangGraph, OpenAI-compatible model routing, and MCP tooling.
- Core GenAI educator at Amex, leading technical sessions on research (MLA, Muon Optimizer, Context Engineering) for 500+ engineers.
- Python Guild AI Lead — drove best-practice architectural decision records for ML/AI and merged the official Amex Python Skill.
- Filed 5+ patents across agentic AI, self-supervised learning, and mechanistic interpretability.
Machine Learning Engineer — Research
Lightsource
- Sole ML Engineer — deployed open-weight GenAI models into production using vLLM across multiple GPUs with dynamic LoRAs.
- Fine-tuned Mistral 7B and Mixtral 8x7B for multilingual content generation using DPO and PPO with synthetic preference data.
- Optimized inference with INT4-FP8 quantization; implemented spherical interpolation model merging for improved multilingual performance.
Director of AI (Part-Time)
Curiouser
- Led engineering for a conversational AI platform. Built LoRA dynamic adapter selection, chain-of-thought tool calling, and autonomous knowledge graph creation for persistent user understanding.
Software Engineer
American Express
- Built production conversational AI using BERT models achieving 90% accuracy across 1M+ monthly interactions.
- Implemented APM monitoring across 100+ microservices using Splunk and OpenTelemetry.
ML Research Assistant
Texas A&M University
- Enhanced SVM accuracy from 79% to 94% through kernel optimization for sentiment classification and cross-border threat detection.
Projects
Open-Source Meta-Harness for Teams of Coding Agents
A coordinator agent turns a research direction into tasks for parallel Claude Code and Codex workers, reviews their work, and settles their objections.
- Workers run in their own project copies with strict limits; the coordinator acts only through checked tools
- Crash recovery and resume, nested transcripts of every agent run, and a record of who allowed each tool call
- In progress: benchmarking and optimizing teams of 8, 16, and more agents on AlgoTune
Agent Improvement Loop with Tamper-Resistant Evaluation
A CLI and agent skill that improves anything scored by a command. The CLI measures, keeps, or reverts each change, so the model never grades its own work.
- Protected files (verifier, tests, spec) are hashed and data paths sealed; editing a protected file stops the run
- Each keep is re-checked on a held-out command that reports only pass or fail
Alignment · ICML 2026 MI Workshop (Accepted, In-Person Poster)
Across twelve open-weight models from five labs, spanning small to frontier scale, the same attention heads carry a 'this is wrong' signal whether the model judges a claim independently or is pressured to agree. The circuit controls deference, not knowledge, and survives alignment training.
- Silencing shared heads flips sycophancy sharply while leaving factual accuracy intact
- Edge-level path patching links the same circuit to sycophancy, factual lying, and instructed lying
- RLHF refresh cuts sycophancy ~10x while shared heads persist, replicated across independent families and anti-sycophancy DPO
Dialogue Tree Search
MCTS-Inspired Synthetic RL Data Generation
A parallel beam search system that treats conversation trajectories as a search tree, using Monte Carlo rollouts to explore diverse dialogue paths. Generates synthetic preference datasets for training tool-using agents via GRPO and PPO with Elo-based scoring.
- MCTS-inspired parallel beam search over conversation trajectories
- Produces preference data for RL fine-tuning of tool-using agents
Energy-Based Model for Constraint Satisfaction
A 36.5M-parameter model combining JEPA-style joint embedding with energy-based inference, solving hard Sudoku through Langevin dynamics in latent space, exploring whether energy-based optimization can substitute for autoregressive generation.
- 96.6% puzzle accuracy, exceeding Kona 1.0’s open-source benchmark of 96.2%
- Forward pass achieves 95.6%; Langevin dynamics adds +1.0% through test-time compute scaling
- Uses mechanistic interpretability to analyze energy-based model reasoning
Transcoder Training Diagnostics
Mechanistic Interpretability
A diagnostic framework for transcoder training failures in mechanistic interpretability. Identified a normalization mismatch causing up to 89% dead features in transcoders trained on Muon-optimized architectures, and developed a diagnostic matrix that predicts which intervention resolves specific training failures.
- Root-caused a normalization mismatch driving up to 89% dead features on Muon-optimized backbones
- Built a diagnostic matrix mapping failure modes to targeted interventions
Education
Georgia Institute of Technology
M.S. Computer Science (Machine Learning)GPA: 4.0
2025 – Present
Texas A&M University
B.A. ComputingGPA: 3.5
2017 – 2022
Awards & Recognition
Published Course Author — Coursera
2023
Authored and published a course on building ReAct agents with the GPT Assistant API, teaching developers how to build autonomous reasoning-and-acting systems.
American Express Inventor Award
2025
Recognized for 5+ filed patents spanning agentic AI, self-supervised learning, and mechanistic interpretability.
Anthropic Bug Bounty Program
2024
Contributed to AI safety through Anthropic’s bug bounty program, identifying vulnerabilities in foundation model behavior.